Just In
Ideas2IT is now an OpenAI Select Partner - recognized to help enterprises build, deploy, and scale AI with GPT-5, responsibly and at speed.
Read the announcement
AI model evaluation usually ends the day a workload goes live. The output clears the bar, the complaints stop, and the model your team picked during the build quietly stays put while the inference bill climbs with every new user. When finance asks why the number is so high, it's hard to say how much of that spend buys results the business needs and how much buys capability the workload never touches.
This guide works through the questions you have to answer before you commit a model to production. It shows how to evaluate AI models on your own workload and what each useful result costs at your expected volume, so your enterprise AI model selection rests on evidence you gathered yourself.
A model choice that looked settled in testing tends to come apart in four places once real traffic arrives.
During the build, your team reached for the most capable model available because the goal was to prove the use case fast. That was a sensible call when traffic was light. Production changes the math. The same choice now gets multiplied by every request your pipeline sends, and a per-request cost nobody noticed in testing becomes a line item finance starts asking about.
Every request carries a system prompt and retrieved context before the user's input even arrives. Provider price sheets typically charge more per output token than per input token, so a model that writes long answers costs more per request even when two models share a similar list price.
A malformed response gets retried, and the retry costs a full call. An output that fails validation goes to a person. Slow responses push teams to add timeouts and fallback models. None of that appears in the price per million tokens, and all of it shows up in what you spend.
Leaderboard rank tells you which model is strongest on general tests. Your workload has a quality threshold, and once a model clears it, extra capability adds no business value. You still pay for that capability on every call, which raises a more basic question about what you should be comparing in the first place.
Model comparison usually collapses into one number, either a benchmark score or a token price. A production evaluation measures six things, and the last one is the number your decision should rest on.
The first five are inputs. Cost per useful result is what they add up to, and getting it right takes more than a price sheet or a leaderboard.
Leaderboards are a reasonable place to start a shortlist. They score models on public tests of reasoning, math, coding and general knowledge. Your workload is narrower and a lot messier.
It might be pulling fields out of claim forms, or answering questions from product documentation through a retrieval pipeline your team built. Your documents are full of domain terms and scanned pages no public test reproduces. There's also a contamination problem. A 2024 survey on benchmark data contamination by researchers at University College Dublin describes how benchmark content can leak into a model's training data, which can make scores look better than real-world performance.
Your production prompt carries a system instruction your team has tuned for months, plus the format rules your downstream systems depend on. That long prompt is paid for on every call, and a model that follows your format rules loosely generates retries a benchmark never counts.
Retrieved documents and tool definitions shape what the model sees, too. A model that handles long, noisy context well can beat a higher-ranked model that loses the relevant passage somewhere in the middle of it.
A benchmark checks if an answer is right. It doesn't check if the output parses into your systems or how many attempts it took to get there. For a view of how the major models stack up by use case and price, our enterprise LLM comparison is a good starting point. The final call still has to come from your own workload.
Before a single candidate runs, write down what the workload is. It sounds obvious, and it's the step that gets skipped under deadline. Profile the task complexity, output schema, daily volume now and in twelve months, latency limits, context size, failure tolerance and quality threshold. That profile earns its keep twice: it rules some models out before you test anything, and it defines what a pass means.
Then build the evaluation dataset from real production inputs covering every input type the workload sees, plus the edge cases your team already knows are trouble. Record an expected output or grading rule for each. Give every candidate the same small budget of prompt changes, because a prompt refined for your current model quietly handicaps every challenger.
With the qualifying models in hand, the instinct is to line up their token prices. That comparison can point you at the wrong model, because price per million tokens only tells you what one attempt costs. It says nothing about how many attempts it takes to get an output you can use.
Four things open the gap between the price sheet and what you really spend:
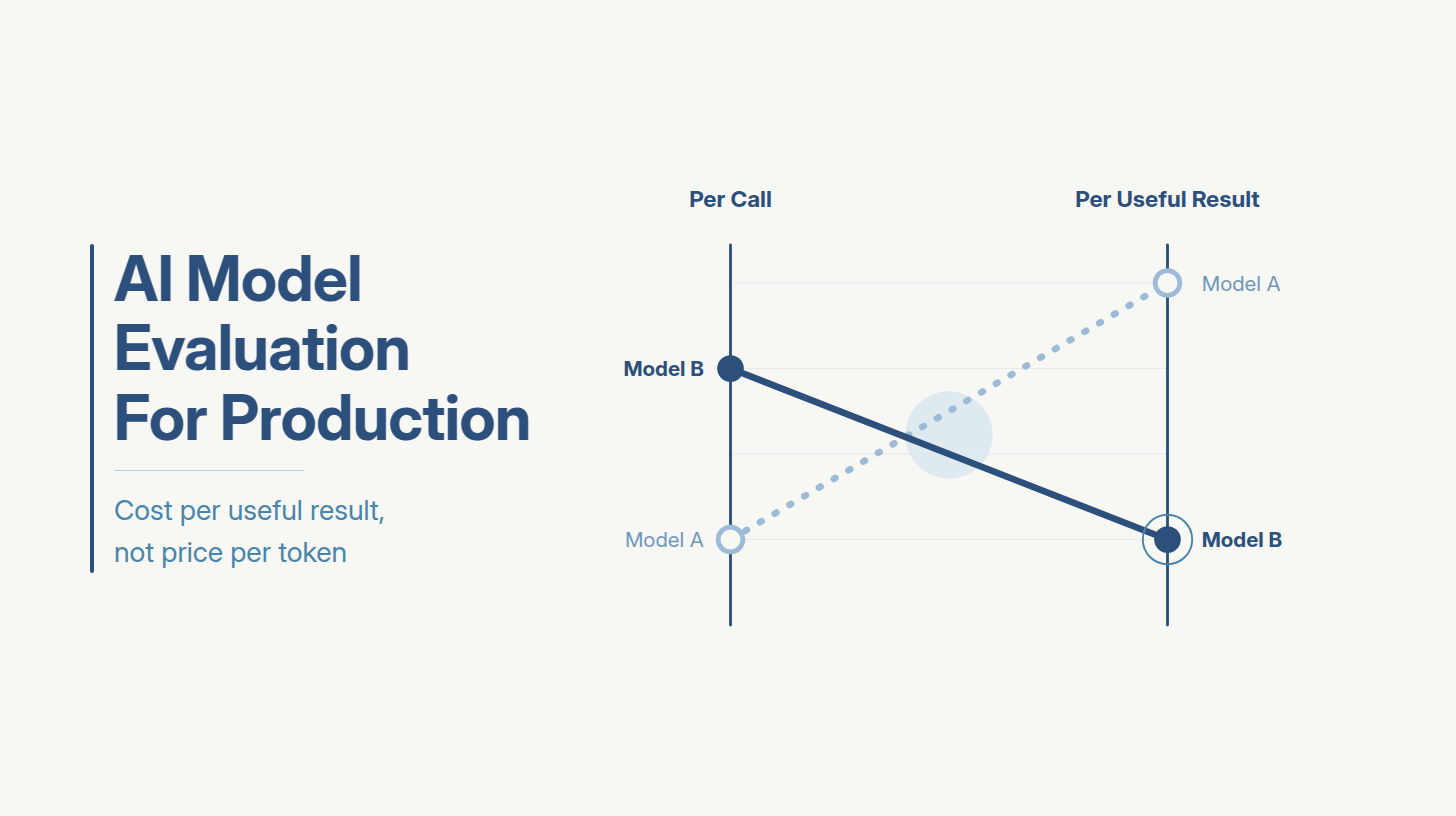
Divide everything you spent across all attempts by the outputs that met your quality bar, and you have an AI model cost comparison that holds up. The table below is a hypothetical illustration, not client data. Both models reach the threshold once retries and review are counted. Where they differ is how often they get it right the first time.
Model A is 40% cheaper per call and almost three times more expensive per 1,000 useful results, because human review of its failures makes up most of the bill. The table doesn't even show the delay each retry adds.
Cost per useful result tends to surface a second problem: the workload is spending tokens it doesn't need, and switching models just moves that waste to a new invoice. If you want to reduce LLM token costs, start with the six sources below.
Caching alone can move the numbers. Anthropic's prompt caching documentation, for example, prices cache reads at one tenth of the base input token price.
Finding the waste is mostly a logging job: split token counts by component, and the biggest line items show up within a day. If the spend you're trying to control sits in AI coding assistants your engineers use, that's a different problem, and our piece on token intelligence engineering covers it.
Once the waste is visible, it's tempting to cut tokens everywhere. Token count is only a proxy, though, and every cut is a trade. Here's how a cut that looks like a saving can end up raising the number that matters:
The cuts that pay back best are usually structural. Asking for output in a defined schema gets rid of wordy free text, and tuning retrieval to your own documents shrinks the input on every call. Order matters here. Optimize on your current model first, then rerun the model comparison, because a model that looked expensive on a bloated prompt can look very different on a lean one. Fine-tuning and distillation come after that, and our guide to LLM optimization covers both.
Rerun your evaluation set after every change, and keep the change only if the pass rate holds. Track tokens per useful result next to that pass rate, and treat a falling token count on its own as unproven.
The cuts that pay back best are usually structural. Asking for output in a defined schema gets rid of wordy free text, and tuning retrieval to your own documents shrinks the input on every call. Order matters too. Optimize on your current model first, then rerun the model comparison, because a model that looked expensive on a bloated prompt can look very different on a lean one. Fine-tuning and distillation come after that, and our guide to LLM optimization covers both.
Smaller models have closed a lot of ground. Stanford HAI's 2025 AI Index reports that the inference cost of a system performing at GPT-3.5 level fell more than 280-fold between November 2022 and October 2024, largely because smaller models got better. That still doesn't make a small model right for every job. It tends to fit when all four of these hold:
Here's a hypothetical example of the third condition. A support team routes tickets into fixed categories, and a frontier model and a much smaller model both sort them at the accuracy the team needs. The frontier model costs more per token and tacks on explanations the parser throws away, so that extra capability gets paid for on every ticket.
Put several workloads through these tests and the results rarely point to one model for all of them. High-volume ticket sorting and low-volume contract review need different quality levels and carry very different costs. Run both on one model and you'll overpay on one or fall short on the other.
The same logic works inside a single workload. Many inputs are routine, and a smaller model can handle those at a fraction of the cost per call. When an input matches a known hard case, or when the small model's first output fails a check, it hands off to a larger model. The expensive model only sees the requests that need it.
Routing isn't free, though. You add a routing layer that needs its own evaluation, and every extra model is one more dependency to monitor and keep current. It pays off when volume is high and some inputs are much harder than others. For a small workload with similar inputs, one well-chosen model is usually the better design.
This is where the evaluation turns into a budget decision. A projection built on your measured numbers needs these inputs:
Carrying the hypothetical Model A and Model B numbers forward shows how a gap that looks small in testing grows with volume.
At a million requests a month, the cheaper-per-call model adds just over $10,000 to your monthly spend.
Divide the projected total by the useful outputs you expect. Then see how it moves if the provider raises prices or retires the model version you're on, because both happen.
A model decision is right for the workload you measured, and that workload keeps changing after launch.
The way to stay ahead of this is to keep measuring. Track cost per useful result on real traffic next to the pass rate, and grade a sample of live requests with the same criteria you used during evaluation. A drop in quality then shows up in your metrics before it shows up as complaints.
Production data also makes your next evaluation better. Add every production failure to the evaluation set, so the next comparison runs against inputs your business actually sees. Agree up front on what reopens the decision: a new model on your shortlist, a price change, measured drift or a big shift in volume.
Pulled together, enterprise AI model selection comes down to seven steps, taken in this order:
Make that last call before the model becomes the company standard. Once it's built into your applications and agents, prompts get tuned to its behavior and parsers start expecting its formatting quirks, and switching turns into a migration project. Keep the evaluation suite ready, so a later switch starts with a test run your team already knows how to do.
Ideas2IT is a platform-led engineering company, so the team running your evaluation also built the production infrastructure it informs. Forward Deployed Engineers embed in your environment from day one and share your team's OKRs. They start by profiling one production workload with the engineers who run it.
In nearly every engagement, the engineering team arrives with a hypothesis about which model they should switch to. The evaluation almost always finds that the current model is fine, and that 30 to 40 percent of its spend goes on retries and human review that tighter prompts and retrieval would eliminate. The model recommendation is rarely the expensive finding. The token waste map is.
From there, the engagement follows the same steps as above:
Where routing is the right design, the FDEs build it on AgentHero, Ideas2IT's in-house AI gateway, which handles model tier routing and provider fallback and enforces token budgets through one interface your platform team controls. Ideas2IT holds SOC 2 Type II certification and is an AWS GenAI Specialist Partner, which matters when the evaluation set comes from production data.
Didn't find what you were looking for?