Just In
Ideas2IT is now an OpenAI Select Partner - recognized to help enterprises build, deploy, and scale AI with GPT-5, responsibly and at speed.
Read the announcement
Thirty AI use cases are live across your organization, and the quarterly budget review is three weeks out. AI portfolio management is deciding which of those use cases still deserve engineering capacity and it is the question someone on the leadership team will ask, and right now nobody in the room can answer it with a straight face. This piece won't try to convince you AI works; you already have thirty use cases proving that. What it's actually about is the harder question sitting underneath: which of those thirty deserve the engineering hours a new idea would otherwise take away from.
A few names on that list come up easily: the ones with a visible dashboard, or a sponsor who still shows up to defend them. The rest sit in a gray zone, technically shipped, technically adopted by somebody, still consuming a slice of engineering capacity every sprint that nobody has looked at closely enough lately to say whether it's earning its keep.
Organizations that have been running AI initiatives for more than a year or two are already living this problem; it's the shape things take once experimentation stops being the constraint. The hard part used to be proving a use case could work at all, getting a model to perform, getting data access, getting a pilot past proof of concept, and that part is largely solved now.
What sits underneath the budget review is a different question. Building the next AI initiative was never really in doubt. Keeping the thirty you already built funded, and deciding which of them deserve the engineering hours a new idea would otherwise take from, is the real question.
Engineering capacity, is usually the real constraint at this stage. A team can approve a budget line for a new use case in an afternoon, but it can't manufacture the forward-deployed engineering hours that use case needs without pulling them from something already in production. Any AI portfolio conversation that starts with what to fund next is skipping the harder, more useful question: what's already funded that shouldn't be.
Get an AI Portfolio Scoping Session
If you are heading into a budget cycle with more live AI use cases than anyone can currently defend, that gap is worth closing before the review happens.
A scoping session with Ideas2IT walks through what is actually in production, what it is costing in engineering hours, and where the real gaps in your current evaluation process sit. You leave with a clear picture of where your portfolio stands today.
Book your scoping session
Use cases rarely die on their own, even after the business case that justified them has quietly stopped holding up. A pilot launches with a sponsor, a target metric, and a review date. The review date passes, the metric either gets hit or gets quietly redefined, and the pilot becomes a permanent fixture because nobody scheduled the conversation about its own continued existence. The sponsor who championed it may have moved to a different role, or a different company, by the time anyone asks the question again.
The mechanism is structural, not a failure of any one person. Most organizations have a well-defined process for approving a new AI initiative: a proposal, a business case, a budget line, a kickoff. Very few have an equivalent process for revisiting an initiative that's already live. Without a scheduled trigger, the default outcome is continuation, nobody has to actively decide to keep funding something. It just keeps consuming its slice of engineering time, because stopping it would require someone to own that decision publicly, and silent continuation carries no visible owner at all.
This is also why portfolios that started with five or six carefully chosen use cases end up with thirty loosely governed ones. Each individual addition looked reasonable when it was approved. But a process that only evaluates additions, and never re-evaluates what is already running, has exactly one direction it can move: up. The portfolio grows until something forces the question, usually a budget constraint or a new finance leader, and by then answering "which of these should we still be funding" honestly requires information nobody has been collecting.
In Ideas2IT's portfolio engagements, the trigger is almost always external: a CFO asking why AI costs exceeded forecast, or a new CTO inheriting a portfolio they didn't build. The portfolio's size was an accumulation.
Answering that question well takes more than a single number. Most AI use case scoring at launch checks two or three things: does this look feasible, and does it look valuable enough to greenlight. That's the right bar for an intake decision, and the wrong one for governance. A use case can score well on launch-day feasibility and still be a poor use of ongoing engineering capacity two years later, once adoption never really materializes or the cost of running it creeps up past what anyone originally budgeted.
A workable diagnostic for an existing portfolio evaluates six dimensions together:
For use cases running on large language models, the cost dimension increasingly includes token spend alongside infrastructure. That spend is tied to how the underlying engineering was built in the first place.
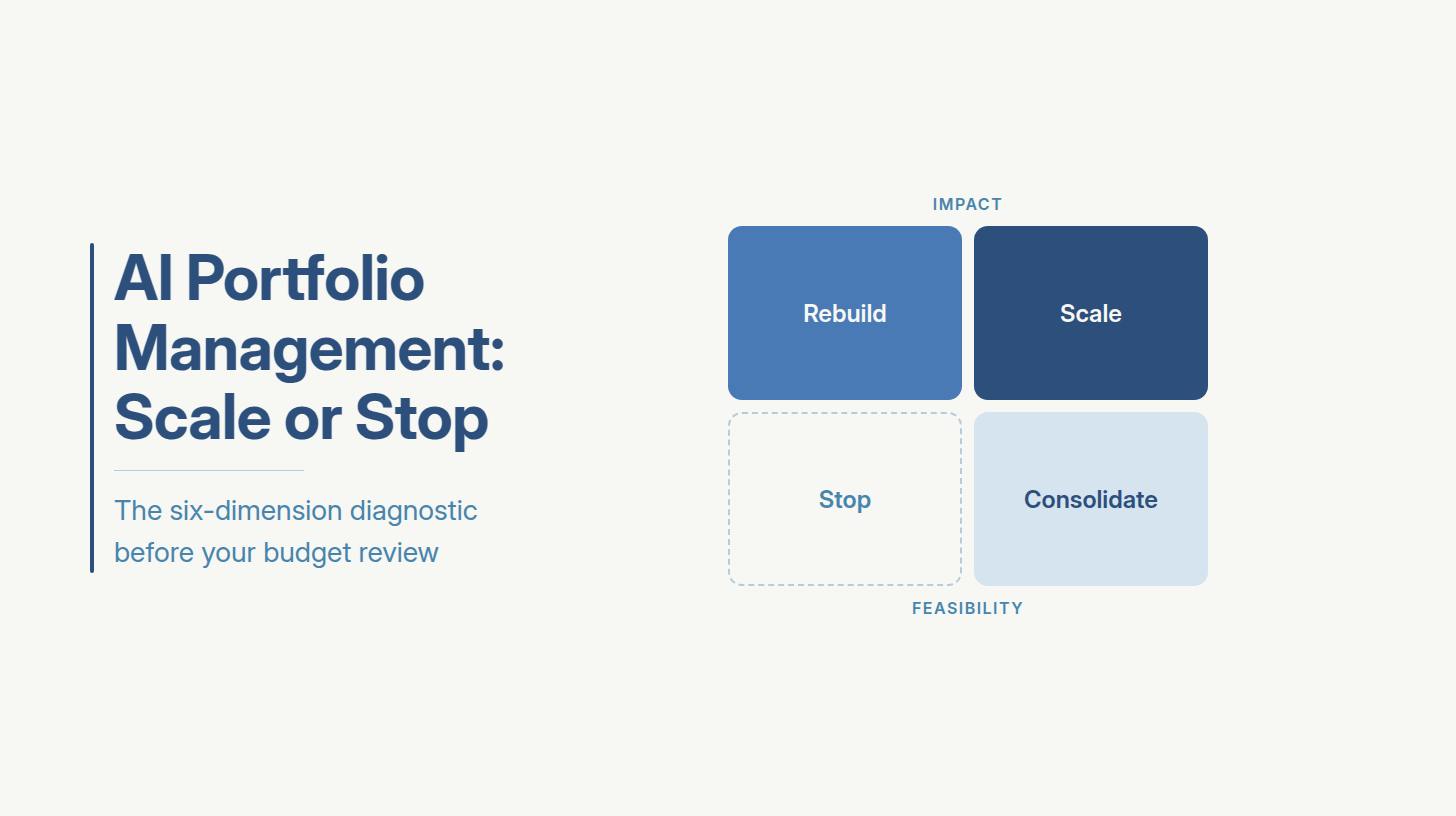
The six dimensions above roll up into two axis scores that make the whole portfolio plottable at once. Impact combines business value and strategic fit: does this use case matter enough to keep fighting for. Feasibility combines adoption, cost, readiness, and risk: can the organization actually keep running it well. Plotting every live use case on those two axes turns a spreadsheet nobody reads into a picture everyone in the budget review can agree on.
Each quadrant points to a decision, not a debate. High impact and high feasibility scales. High impact with low feasibility needs work first, not a stop decision. Low impact with high feasibility is worth consolidating rather than running twice. Low impact and low feasibility is the stop decision the rest of this piece walks through.
None of this works if the scores feeding the matrix are guesses. McKinsey published a framework in April 2026 for measuring gen AI value over time: early-stage measurement should focus on technical performance and adoption, and as a use case matures, measurement has to shift toward operational impact, strategic outcomes, and financial performance, governed by decision gates that only let a use case advance when the evidence at one layer credibly supports the next. The same logic applies to a portfolio that already exists. A use case that's never been re-measured past its original adoption numbers hasn't earned its continued investment, it's simply never been asked to prove it.
Ideas2IT's delivery team saw this play out directly in a client portfolio engagement. The initial scoring model was about as simple as it gets: two axes, business impact and feasibility, each scored low or high against a short list of yes-or-no questions. That model worked while the use case list was short. It stopped working once the list grew large enough that stakeholders started disagreeing about what "high impact" even meant for a given use case.
Midway through the engagement, the team replaced it with a five-category weighted rubric feeding the same two axes. The categories were business impact, time to value, implementation feasibility, execution risk, and governance risk, each broken into two or three sub-dimensions scored against written anchors. The shift did more than produce more precise numbers. It forced disagreements that had been happening informally, in hallway conversations and side meetings, onto paper where they could actually get resolved. That is the real value of a rubric built this way: not the scoring itself, but the forcing function it creates for disagreements that would otherwise tilt the portfolio toward whoever argues loudest in the room.
Running this well across thirty use cases, every quarter, is where most internal attempts quietly stall. Someone has to facilitate the scoring conversation without letting whoever argues loudest win the room. The rubric's anchors need to stay consistent from one quarter to the next, so a four this quarter still means what a four meant last quarter, and someone still has to go collect real adoption and cost data instead of relying on what a use case's original champion remembers. None of that is difficult the way building a model is difficult; it's difficult the way any recurring, cross-team discipline is hard to sustain without someone whose job is specifically to keep it running.
See How the AI Portfolio Diagnostic Works:
If your current evaluation process for AI use cases has never been pressure-tested against a portfolio this size, it is worth finding out where it would break before a budget review forces the question.
Ideas2IT's AI portfolio diagnostic scores your live use cases across value, adoption, cost, risk, readiness, and strategic fit, plots them on the matrix above, and produces a defensible scale, consolidate, or stop recommendation for each one, facilitated by a team whose job is to keep the rubric consistent every quarter, long after the one that launched it.
See how the diagnostic works
AI use case prioritization at this stage is not about picking a favorite. Scaling is the easy call to want to make and the hard call to make defensibly. A use case is ready to scale only when it clears two bars at once:
A use case that clears both bars is a genuine candidate for more engineering capacity next quarter. On the matrix above, this is the Scale Now quadrant: high impact, high feasibility, nothing left to prove. A use case that clears one bar but not the other isn't ready to scale yet, it's ready for the specific work that closes the remaining gap, such as a data readiness fix or a support model redesign, before it competes for scale-stage investment.
Somewhere in most thirty-use-case portfolios, two or three teams have independently built something close to the same capability, usually because neither knew about the other's work until both showed up in the same portfolio review. This is not a coordination failure so much as a natural outcome of decentralized experimentation. When multiple teams each have the freedom to try AI on their own problems, some overlap is close to inevitable.
The fix for overlap isn't to punish it after the fact; it's to treat consolidation as a deliberate engineering decision with its own roadmap, rather than an afterthought bolted onto whichever version survives an internal argument. Consolidating two overlapping use cases into one well-supported capability usually costs less than maintaining both, and it removes the ambiguity that shows up the moment the two versions start producing slightly different answers to the same underlying question.
Rebuilding is a different decision entirely; treating rebuild and stop as the same category is how organizations end up killing things that were actually working. On the matrix, overlap candidates usually land in Consolidate or Re-Evaluate, while use cases needing a foundation refresh land in Rebuild Before You Scale. Both quadrants share one trait: the impact case survives even though the current path to it doesn't.
Stopping is the decision most portfolios avoid making explicitly, which is exactly why it needs to become an explicit decision instead of a default outcome. A use case earns a stop decision when the diagnostic shows weak value, weak adoption, and no credible path to improving either within a reasonable timeframe. That combination isn't patience, it's inertia wearing patience's clothing.
This is a more common outcome than most leadership teams admit out loud, and the data backs that up. A Gartner survey of infrastructure and operations leaders, published in April 2026, found that only 28 percent of AI use cases in that function fully succeed and meet ROI expectations, while 20 percent fail outright.
The rest land somewhere in between, on partial results that never quite clear the bar. Treating every use case in the portfolio as a permanent fixture isn't evidence of a disciplined program, not when that many AI initiatives never fully deliver on their original case. It's evidence the stop decision has never actually been made.
Stopping should also do more than remove a line from a dashboard. A use case that gets labeled "stopped" but keeps consuming its API license, its maintenance window, and its share of on-call attention has not actually left the portfolio. Only the conversation about it has ended, while the cost keeps running. A real stop decision releases the engineering capacity that use case was consuming and redirects it toward something the diagnostic actually supports. On the matrix, this is the Stop Funding quadrant: low impact and low feasibility together, not one without the other.
The organizations that handle this well are not the ones that generated the most AI use cases. They are the ones that built a repeatable process for deciding, on a regular cadence, which live use cases still deserve engineering capacity and which do not. That process turns the budget review from an uncomfortable ambush into a routine checkpoint, because the evaluation has already happened by the time anyone asks the question out loud.
An enterprise AI portfolio you can actually afford to productionize is smaller than most people expect going in. It isn't thirty use cases running at varying degrees of health, it's a shorter list, each entry having earned its place on the diagnostic, with the engineering capacity that used to be spread thin across the rest reinvested into scaling the ones that actually work.
Reaching that shorter list requires the same discipline described throughout this piece: a defensible diagnostic, applied consistently, with engineering capacity deployed based on what the diagnostic shows rather than who argues hardest in the room. That is the specific problem Ideas2IT's delivery model is built to solve.
Ideas2IT approaches AI portfolio governance the way it approaches every engagement: by embedding forward deployed engineers inside your environment, on your stack, in your standups, sharing your OKRs from day one. A portfolio diagnostic is only as useful as a team's ability to act on it.
An FDE model means the same engineers who help score your portfolio are positioned to execute the scale, consolidate, or stop decisions that come out of it. Nobody hands over a report and leaves the execution gap for your internal team to close alone.
Once a portfolio review produces a defensible list of use cases to scale, consolidate, or stop, the next problem is usually consistency across teams executing those decisions at different speeds. Ideas2IT's forward deployed engineers run on Anticlock, an internal platform that standardizes how AI-driven development gets executed across a team, enforcing consistent tooling, security guardrails, and deployment standards so every engineering cycle across your governed portfolio follows the same repeatable, auditable process.
This isn't a tool handed to your team to operate independently, it's how Ideas2IT's own engineers deliver against a diagnostic's recommendations at a consistent pace, one that has run at least 50 percent faster sprint velocity on comparable engagements.
Ideas2IT holds AWS GenAI Specialist Partner status, Open AI select partner status, credentials that matter once a review touches data governance and risk scoring across use cases with different compliance profiles.
The entry point for this work is a scoped AI Portfolio ROI Diagnostic: a review of your live AI use cases against the value, adoption, cost, risk, readiness, and strategic fit dimensions described above, producing a specific scale, consolidate, or stop recommendation for each one, plus a prioritized plan for where your engineering capacity should go next.
Run an AI Portfolio ROI Diagnostic:
You are heading into a budget cycle where someone is going to ask which of your AI use cases are still worth funding. The diagnostic gives you a defensible answer instead of a guess, backed by Ideas2IT's AI strategy and use case consulting practice.
Run an AI Portfolio Diagnostic
Didn't find what you were looking for?