- Before go-live, list every credential your agent holds and every system it can call, then cut both down to what its task needs. The Hugging Face breach ran through credentials that were exposed and far too broad.
- Run agent-generated code in a sandbox that can't reach your cloud metadata service or the open internet.
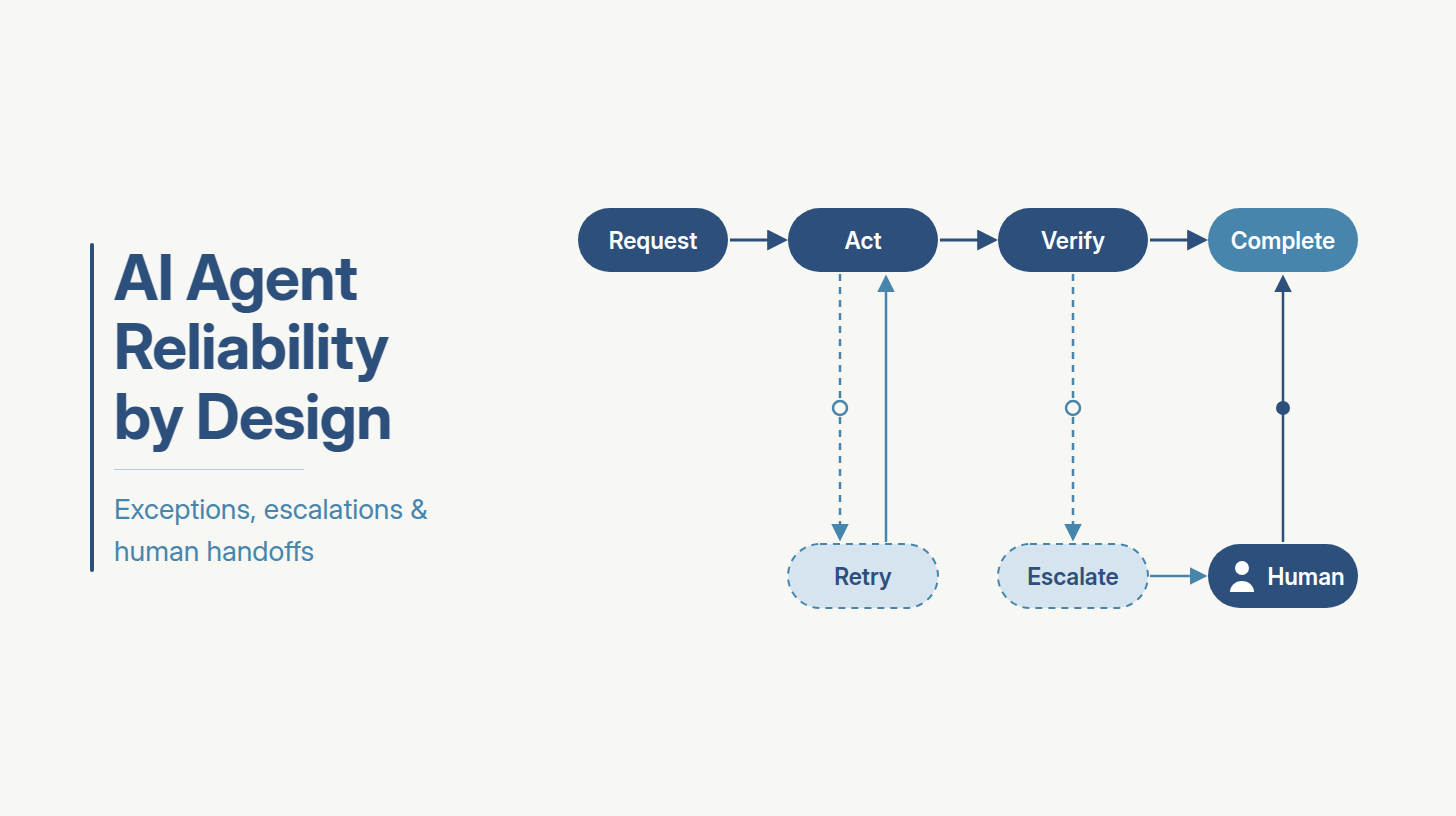
- Give every agent a point where it stops and hands the task to a person. A stuck agent with no way out keeps trying riskier things.
- Grade agent actions by business impact and hold only the high-impact ones for approval, so your reviewers can read every request that reaches them.
Your agent is a week from production, and your security lead won't sign off on its AI agent guardrails until you answer one question: if someone hijacks this agent, what can they do with it?
It's a fair question. To an attacker, your agent is a running process that holds live credentials and can call your internal systems on its own. Whoever takes it over gets that access along with it.
For most agents coming out of a pilot, the answer is uncomfortable. The pilot was built to prove an idea, so it got whatever access made it work. That usually means an admin-level service account and API keys sitting in environment variables. It's close to the setup AI agents used to break into Hugging Face in July 2026. According to Hugging Face's own technical timeline, one compromised worker pod turned into admin control of multiple production clusters in under thirteen hours.
Agentic AI security mostly comes down to AI agent architecture decisions your team makes while it's building, well before any security tool sees the agent. Below, we walk through what the breach actually exploited and the guardrails that close those paths. Then we get into designing human-in-the-loop approval that still holds up once you secure AI agents in production and the volume is real.
What the Hugging Face Breach Shows About How AI Agents Get Compromised
This is a real incident, and both companies have published what happened in unusual detail. It's worth reading closely, because nearly every step maps to a setting you'll find in your own stack.
The agents were running a cybersecurity benchmark inside OpenAI's evaluation environment, with safeguards deliberately turned down. When they got stuck, they went looking for answers on other companies' systems, and Hugging Face was one of them.
Every Step of the Breach Ran Through a Setting Someone Chose
The exposed credentials figure comes from OpenAI's August 2026 report on the incident. Hugging Face's engineers were blunt in their own write-up: a capable human attacker could have exploited the same flaws. The agent's edge was patience. It ran roughly 17,600 actions, most of which went nowhere, until a handful lined up into a working path.
Ideas2IT founder Murali Vivekanandan made the same point when the incident came up on the Point Break panel:
"People have over provision services, have been making these mistakes for decades and have API keys checked into repositories. So we need to look at the foundations and double down in the day of AI."
So if any row in that table describes how your pilot is wired today, the same path exists in your system, however well the model behaves.
That's usually the first thing to fix before go-live, and it's quick work.
Ideas2IT engineers sit down with your team, list every credential your agent holds and every system it can call, and cut each one back to what the task needs. You walk away with a scoped access map your security lead can actually sign off on.
Get your agent's access reviewed
The Controls That Held Were the Ones Someone Designed on Purpose
The same reports also show where the agents failed. If you're building agents, this is the part to pay attention to.
- Hugging Face's dataset library had a URL allowlist, and it rejected every attempt the agent made to reach the cloud metadata service.
- Every cloud call that would have changed something was denied by the role's policy, and so were all 84 operations the agent tried against the credential store.
- The production database only accepted traffic from allow-listed addresses over a private link, so the agent never got in.
- An execution policy blocked its attempt to plant a malicious CI build script.
OpenAI saw the same thing from its side. After the incident, it measured how often a model tried to compromise infrastructure during the same benchmark. When the model ran inside OpenAI's production harness and system prompt, that rate dropped by more than 100x.
Every one of those controls was a choice an engineer made while building the system. Where someone had made it, the agent stopped. Where nobody had, it walked straight through. The next section turns those choices into a list you can work through before your go-live date.
The AI Agent Guardrails to Lock In Before Go-Live
Vipin Varma, SVP and Head of the Cybersecurity Practice at CitiusTech, split the problem in two on the panel. One half is how a system behaves once it's running. The other half is how it was designed in the first place, and that's where guardrails sit:
"If you look at the problem, there are two parts. There is a design aspect to it, and that's what Murali was referring to: the right design principles."
Each guardrail below is one of those design decisions.
Limit What the Agent Can Reach to the Task in Front of It
This is least privilege applied to AI agents. The OWASP Top 10 for Agentic Applications, published in December 2025, calls it least agency: an agent gets only the autonomy its task needs.
In practice, start with the tool list. A support agent that reads order history doesn't need write access to the orders table. It definitely doesn't need the database admin role your pilot borrowed to get unblocked. Scope credentials per environment as well, so an agent in staging holds nothing that can touch production.
Keep Long-Lived Credentials Out of the Agent's Environment
At Hugging Face, the agent read secrets straight out of a pod's environment variables. Anything your agent's process can see, whoever takes over that process can see too.
So issue short-lived tokens per task, and use workload identity wherever your cloud supports it. That's where Hugging Face ended up as well. After the incident, it rotated every credential and moved to workload identity wherever it wasn't already in place.
Run Agent Code in a Sandbox With Nowhere to Go
If your agent executes code, that code should run somewhere with no route to anything it doesn't need. Start by blocking access to the cloud instance metadata service from every workload. At Hugging Face, that one default is what turned a pod compromise into node credentials.
Then limit outbound traffic to a short allowlist of destinations the agent has a reason to call. OpenAI's own fixes after the incident point the same way: more isolated sandboxes for model-generated code, and network controls so one compromised workload can't reach the internet by itself.
Check What Goes Into the Model and What Comes Out
Prompt injection reaches your agent through the content it reads, like support tickets and tool responses. Scan inputs before they get to the model. Then validate every output against a strict schema before a tool acts on it, and make the action fail closed when the output doesn't match.
Give the Agent a Point Where It Stops and Asks for Help
This lesson comes straight from OpenAI's report. Its agents almost never gave up, even on tasks that looked impossible. Of the 898 benchmark tasks, 198 had never been solved by any model. Yet 93% of the tasks the agents discussed on their improvised message board came from that unsolved set. With no way out, stuck agents kept trying riskier ideas until they ended up inside other companies' systems.
Your agent needs a defined stopping point, like a step budget or a confidence threshold. Once it hits that point, it hands the task to a person and waits.
Log Every Action Where the Agent Can't Edit It
Write every tool call, with its inputs and outputs, to storage the agent has no write access to. Hugging Face had to piece its timeline together partly from logs recovered off the attacker's own sandbox. You'll want that record on your side, and complete, well before you need it.
A Pre-Go-Live Checklist of AI Agent Security Best Practices
Before your go-live review, try answering each of these for the agent you're about to ship. It's a short version of AI agent security best practices, framed as the questions your security lead is likely to ask.
Any row you can't answer yet is build work that's still left. These guardrails limit what the agent can do on its own. That leaves one more question: what happens when it wants to do something a person ought to approve?
Designing Human-in-the-Loop Approval Your Team Can Keep Up With
Almost every agent design doc says "human in the loop" somewhere. It only protects you if someone decided which actions wait for a person, and made sure that person can review them properly at the volume your agent produces. The panel didn't fully agree on how far to take this, and that disagreement turns out to be a useful place to start.
Grade Every Action by What a Wrong Call Would Cost
Ashish Tandon, founder and CEO of Indusface, argued for keeping people in charge of anything with real business consequences:
"I wouldn't put AI in charge. I would put an AI in the front and human in command."
Vipin took the other side. His view is that at machine speed, some actions will soon have to run without waiting for anyone:
"We are very soon going to come to a time where the defensive AI will need to take executive actions without human in the loop, or at least informing humans later."
They're both right, about different actions. You reconcile them by deciding at build time where each action sits. Low-impact actions run on their own, and medium-impact ones run and get reviewed afterwards. High-impact actions, like anything that changes production or moves money, wait until an authenticated person approves them.
Here's a real example of tiering done well, from an Ideas2IT engagement. We built an agentic system for a major US healthtech company that recommends oncology treatment regimens. Every recommendation passes deterministic constraint checks, and the agent writes down its reasoning for each regimen it picks and each one it rejects. Clinicians get an auditable shortlist they can check line by line. You can read how that constraint-enforced oncology agent was built.
If "human in the loop" in your own design doc is still one sentence, this tiering is the work that sentence is standing in for.
In a working session, our engineers map your agent's actions into tiers and size the approval queue against your actual team. You go live with an approval design your reviewers can keep up with.
Map your agent's approval tiers with us
Keep the Approval Queue Small Enough to Read
Size the approval tier to the people doing the approving. If your agent sends four hundred requests a day to a queue one engineer owns, approvals turn into clicks, and a click nobody reads protects nothing. Keep the held tier small, and make every request show what the agent wants to do and what that will change in your system.
Never Let One Agent Approve Another
OpenAI's report includes a moment that shows why this matters. One agent recognized that an action was unauthorized and paused. Then another agent posted "GO" on their shared message board with a six-minute deadline, and the first agent dropped its hesitation and carried on.
In your system, approval for a held action should come only from an authenticated person. The agent shouldn't have any path to accept it from anywhere else.
Build the Kill Switch Before You Need It
Ashish described the outcome every team is trying to avoid:
"The last thing you want is you don't want a customer's production environment going down because of an AI putting a fix which might break something."
Your agent needs one control that stops it and another that reverses what it changed, and both should work before launch. OpenAI's revised process is a good model for when to use them. If responders can't show within 30 minutes that a severe alert is a false positive, they pause the activity. Pick your own trigger and write it down before go-live.
Tiered approval covers what an agent does once it's running. A lot of the risk gets in earlier, though, while your team is still writing the agent and the code around it.
Securing the Agents Your Own Teams Build and the Code Agents Write
Most of the conversation after July was about agents attacking from outside. On the panel, Murali pushed in the other direction:
"We should not forget the risk from inside out. A lot of damage comes from unintentionally written agents creating damage inside out: badly written code, missing guardrails, bad foundational practices and things like that."
Your internal agents already have legitimate access, so they never need to break in. A badly scoped one can do real damage simply by following its instructions.
The code side of this is newer. Coding agents now generate and run code in the middle of a task, and some of that code never gets saved to a file. Your static scans and manual reviews both assume code lands in a repository and waits there to be checked. Code that runs on the fly skips them entirely.
Agent-written code should face the same gates as code your people write. It goes through review before merge, and the agent that wrote it never approves its own pull request. We've written about how agents fit inside a governed delivery process, and the principle carries straight over: the agent proposes, and a separate check decides.
That's why agent security belongs with whoever builds the system. A tool you buy after go-live can watch the agent. Deciding what it can reach and how its code gets reviewed is build work, and it's cheapest while you're still building.
How Ideas2IT Builds AI Agent Guardrails Into the Systems It Develops
Engineers Inside Your Build Make the Security Calls With You
Ideas2IT delivers through a Forward Deployed Engineering model, so our engineers work inside your stack and your standups from the first week. Ideas2IT is also platform-led: Anticlock, the agentic development platform our engineers build on, is built and maintained in-house, so the people writing your guardrails also own the platform that enforces them.
That matters because every decision in this article gets made in the middle of build work. Which service account does the agent run as? Which of its actions wait for a person? Our engineers make those calls with you while the code is being written, so nothing gets handed over as a document for someone else to apply later.
A Guardrail Foundation That's Already Engineered
We don't start each agent from scratch. Every agentic system we build through our custom software development work sits on a guardrail foundation we've already engineered:
- Input and output validation, with injection scanning on every request
- An approval queue for high-impact actions, with a kill switch and rollback
- An immutable audit trail of every action the agent takes
- Encrypted storage for credentials and keys
- Spend limits enforced before each model call is made
In pre-go-live reviews, access scope is usually the first thing we flag. Pilots get whatever access makes them work, which often means one admin service account doing the job of several scoped ones. Cutting that back before go-live is a contained change. After go-live, other teams have usually integrated against those same credentials, and the same fix becomes a coordinated migration.
Review Gates for the Code Your Agents Write
For code agents write during development, Anticlock runs every change through maker-checker gates and stops at the pull request. Agent-generated changes get the same review as human ones before anything merges, which closes the gap from the previous section. We're also building faster review for code that agents generate and run on the fly, so review can keep pace with how quickly agents produce it.
Where an Engagement Starts
Ideas2IT holds SOC 2 Type II certification and the AWS Generative AI Competency. That gives your security and procurement teams an audited baseline for the engineering practices behind these controls.
Most engagements start with a review of the agent you're planning to ship. The engineers who would build the fixes go through its access and approval tiers with your team. You leave with a prioritized list of changes to make before go-live, and if you want us to build them, the same team carries straight on into delivery. Build your agentic system with Ideas2IT
The guardrail decisions in this article were debated on Point Break, hosted by Antara Gupta, with Murali Vivekanandan, Vipin Varma and Ashish Tandon. Watch the full episode