- If your eval scores look steady while the business says quality has slipped, start with what your evaluation measures and who defined it. The model is rarely the first thing to fix.
- Rebuild your test set from recent production traffic and have a business owner sign off on the criteria. Then check your LLM judge against their pass or fail calls before you rely on it.
- Before you tune another prompt or buy another platform, find out how often your eval score and your business owner disagree on the same outputs. That one number tells you how much to trust everything else on the dashboard.
- Model swaps and expansion approvals both rest on a quality number the business believes. Fixing the definition of good is what makes those calls defensible.
You've probably sat through some version of this review. Your AI evaluation and observability dashboard shows faithfulness and relevance holding steady for four releases, and the LLM judge passes nine responses out of ten. Then the head of customer operations mentions that her team rewrites drafted replies so often they've stopped counting, and asks why that isn't on the dashboard anywhere.
It's a fair question. Your stack records what the system did on every request, but it can't tell you whether the business would have accepted the answer. That blind spot shows up in plenty of AI agent observability and evaluation setups, and it's where the business's trust starts to slip, usually months before anyone calls it a quality problem.
What AI Evaluation and Observability Each Tell You
Evaluation and observability answer different questions, and each one fails in its own way without the other.
The complaint in that review usually means you have both, and neither one is measuring what the business needs.
Why AI Evaluation Scores and User Complaints Disagree
Your eval suite answers the question your team settled at design time: does this output meet the AI evaluation metrics we wrote down? Your business owner is asking something else every day. She wants to know if she'd put her name on it. Both answers can be accurate and still point in opposite directions.
You're far from alone here. LangChain surveyed 1,340 practitioners at the end of 2025 for its 2026 State of Agent Engineering report, and the gap shows up clearly in the results:
- 89% have some form of observability on their agents
- 52.4% run offline evals against test sets
- 37.3% evaluate live traffic
- Quality is the top barrier to production, for the second year running
So most enterprises can see every step their AI took, and far fewer can say with confidence that the result was good. Fewer still have handed that judgment to the person who owns the outcome. Among the largest companies in the survey, hallucinations and inconsistent outputs came up as the hardest quality problems, and both are easy for an averaged score to hide.
How to Measure the Agreement Rate Between Your Evals and the Business
The most useful number for closing this gap is the agreement rate, and measuring it takes no new tooling.
- Pull a sample. Take 200 real production outputs from one application.
- Score it your way. Run your current eval suite on all 200.
- Score it the business's way. Have the business owner judge the same 200 independently, without seeing the eval results.
- Compare. The agreement rate is the share of cases where both verdicts match.
The disagreements are where the value sits, and they come in two kinds.
A low rate means your evals are measuring something the business doesn't recognize as quality. A very high rate on the first check deserves a second look too, since it can mean the owner hasn't seen enough edge cases yet. Either way, the number matters less than what the disagreements show you.
See how far your eval scores sit from production
When the dashboard and the business tell different stories, the first job is measuring the distance between them on real traffic. A working session takes one production application and compares its eval scores with how the business judged the same outputs.
Compare your eval scores against production
That gap rarely comes from one place, which is why tuning prompts against the current scorecard so seldom closes it.
Four Places Your AI Evaluation Drifts From the Business
There are four places to check first, and none of them needs new tooling.
A test set frozen at launch
The eval set is usually written in the weeks before go-live, by people guessing what users will ask. Once real traffic arrives, the mix of requests shifts, and the frozen set keeps grading the system on questions users have stopped asking. Scores stay flat while the cases that actually reach customers go unmeasured.
Criteria written only by engineers
Engineers check what they can see in an output, like grounding and format, while the business judges tone and policy. In a 2024 study, Annalisa Szymanski and her co-authors compared the evaluation criteria domain experts wrote with criteria from lay users and from LLMs. They concluded that experts need to be in the loop early, because developers working alone lack the domain knowledge to set criteria that hold up.
An LLM judge nobody calibrated
It's easy to assume an LLM judge is objective because it isn't a person. Look at how it was built, though. An engineer wrote the prompt, using criteria an engineer chose and examples an engineer labeled.
An uncalibrated LLM judge is one engineer's opinion, automated.
Until someone checks that opinion against the business owner's, the pass rate doesn't deserve anyone's trust, and a high one can mislead people more than a low one would. Hamel Husain, who has helped more than 30 companies set up evaluation systems, lists unvalidated metrics among the mistakes he sees most. He builds judges from an expert's pass or fail calls with written critiques, then tests them against those calls.
User behavior that never leaves observability
Your traces record every edit and escalation, but those signals usually live in a monitoring tool nobody on the eval side reads. The behavior that best reflects your business owner's judgment sits right next to the evaluation without ever feeding into it. The section on observability signals further down covers how to connect the two.
Together, those four causes create costs the business feels long before your engineering metrics move.
What the Eval Gap Costs Before Anyone Calls It Quality
Trust in your numbers goes first: Once your business owner has seen a green dashboard next to a team that's rewriting outputs by hand, she'll discount every score you show her after that, accurate ones included.
Workarounds start where you can't see them: People who don't trust the outputs check everything themselves, and the efficiency case behind the application quietly wears away. Your usage numbers still look fine, because people are still calling the system.
Engineering effort goes to the wrong target: Your team spends sprints tuning prompts and retrieval to push up a score the business has stopped believing. A release that adds two points of faithfulness can still make the owner's week worse, and nothing on your dashboard will show it.
The next decisions slow down: Moving to a cheaper model needs a sponsor who believes the current system works, and so does every request to roll the application out to another function.
Some of that cost comes from asking one kind of evaluation to do a job it was never set up for.
Offline vs. Online Evaluation: What Each One Should Catch
Offline evaluation runs a fixed test set before each release, so it's good at telling you if a change broke something you already knew to check. Online evaluation scores a sample of live traffic after release, so it catches the requests nobody thought to write a test for.
Offline evals are useful. The trouble starts when they're the only evals you run. Your test set was written before users arrived, by engineers imagining what users would ask. Real users bring phrasings and edge cases nobody anticipated, and by the time that gap shows up on the dashboard, the business owner has usually stopped trusting the scores.
LangChain's survey suggests plenty of programs fund the first and skip the second. Among respondents with agents already in production, 44.8% run online evals, compared with 37.3% across the whole sample, and only about a quarter of organizations running evals use both approaches.
If your evals never see live traffic, they can't see the requests your business owner is complaining about. Online evaluation is the part of LLM evaluation in production that does.
Put a number on the gap before your next budget review
Right now there are two versions of quality in play, and the one your sponsor believes isn't on your dashboard. Nobody has checked how often your eval score and your business owner agree on the same outputs. A working session samples real production interactions from one application, has the owner judge them, and hands you the agreement rate plus the exact places where the two split.
Book an eval gap working session
Getting that split right still leaves the harder question of who decides what passes.
Rebuilding AI Evaluation Around What the Business Counts as Good
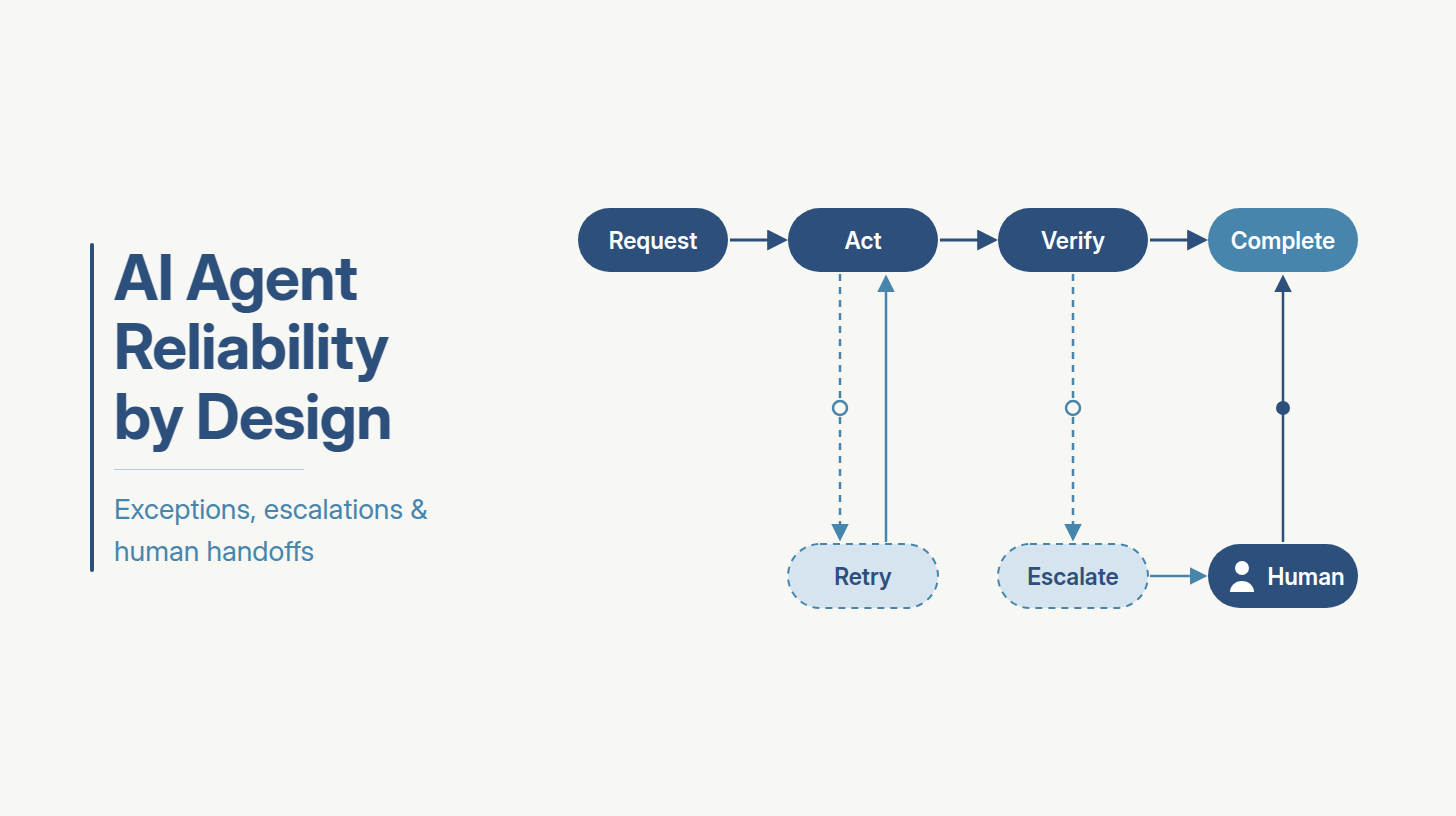
None of this needs new tooling. Testing how an agent behaves when a tool fails is a separate job, covered in your agent reliability testing. Three changes do most of the work here.
- Give each application one owner for quality. Pick one person on the business side and make their judgment the definition of a passing answer. They make pass or fail calls on a sample of real outputs and add a sentence on each failure. When the owner and engineering disagree, the owner wins and the case goes into the test set.
- Rebuild your test set from production traffic. Swap the pre-launch eval set for a sample of recent production interactions and refresh it on a fixed schedule. Keep the old set as a regression floor, and version every set so you can tell a system change from a test change.
- Show judge agreement next to every score. Before an LLM judge's score goes on a dashboard, check how often it agrees with the business owner, and publish that rate beside the score. A 92% pass rate from a judge that matches the owner 60% of the time doesn't tell you much, and your sponsor should know which kind of number they're looking at.
The owner's role only works if what they write down can actually be scored, which is where most rubrics fall apart.
Writing Evaluation Criteria the Business Can Sign Off On
Generic metrics like faithfulness and relevance are useful to your engineers, but a business owner can't sign off on a score of 0.87. They can sign off on a sentence.
Start with pass or fail. Husain recommends binary judgments, each with a short written critique, over 1-to-5 scales. A critique explains the call, and it can later become a worked example for your LLM judge. Score scales mostly produce arguments about the difference between a 3 and a 4, which nobody on the business side cares about.
Then turn the critiques into criteria. Here's a hypothetical from a customer support application, showing one criterion before and after the business owner has reviewed real outputs.
An LLM judge can score the second version. The first one gets scored on whatever the judge decides helpful means.
A criterion is ready to use when:
- the owner would reject a failing output on sight
- it's written in words the owner uses herself
- it describes a failure she has actually seen in production
- a judge can apply it without guessing what a vague word means
Revisit the list whenever the owner fails an output the rubric doesn't cover. That usually means she's applying a rule she hasn't said out loud yet.
Criteria cover what the owner reviews. Observability covers the much larger share of traffic she'll never see.
Turning Observability Signals Into AI Evaluation Data
Your traces already record what people did after each response. At full traffic volume, that behavior is the closest thing you have to the owner's judgment, and it often never reaches the eval suite.
Each cycle, route the interactions with the strongest negative signals into the owner's review queue, so the complaints the business raises are the first cases your evaluation sees. You also get a business-facing number almost for free. When the rewrite rate falls while your eval score rises, the two are finally telling the same story, and agent observability and evaluation start working on the same problem.
With signals flowing in, the remaining risk is that nobody clearly owns any of it.
Who Owns What in AI Evaluation
Eval programs tend to stall on ownership, so write the split down before you build anything. Here's a starting point for a single application.
Two details decide if this holds up:
- The owner's review has to fit inside a normal week. A well-chosen sample matters more than coverage.
- The agreement rate needs a named owner on the engineering side. Without one, it turns into a number everyone looks at and nobody acts on.
Ownership keeps the work running. Reporting is what keeps it funded.
Reporting AI Evaluation Results Your Sponsor Will Trust
A dashboard of faithfulness and relevance scores is built for your team. Your sponsor reads it as a claim they have no way to check, so lead with numbers they already recognize.
Once your sponsor sees evaluation changing decisions, the next budget conversation gets a lot easier.
None of this has to start everywhere at once.
Where to Start: One Application, One Number
- Pick the application the business complains about most. The owner there already has a reason to give you their time.
- Run the agreement-rate check on 200 of its recent production interactions, with a one-line reason on every fail.
- Match the disagreements to the four causes. The owner's reasons will tell you which one you're dealing with.
- Fix that application's measurement and show the owner the agreement rate going up.
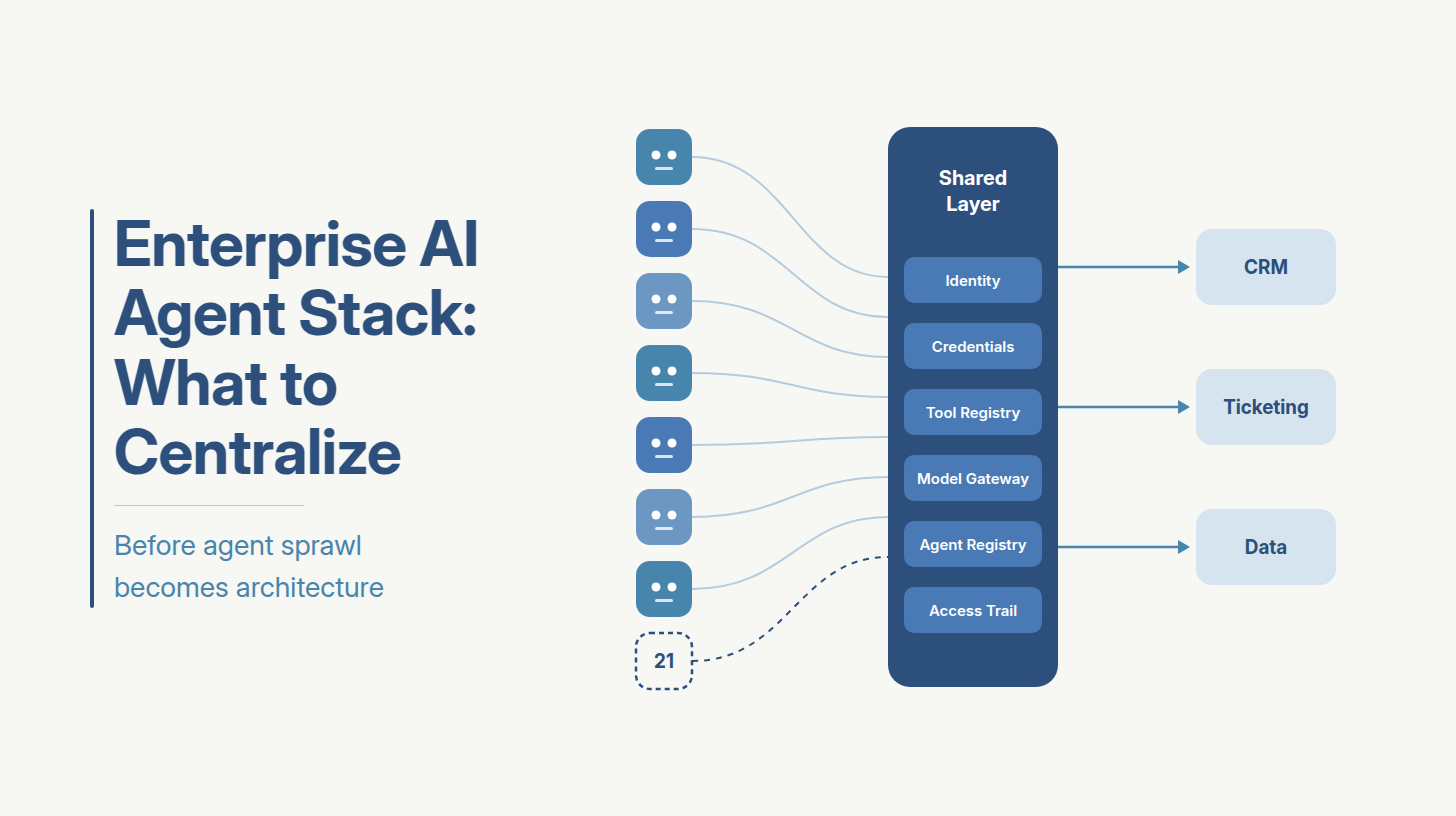
- Then extend the pattern. Once a second and third application have owners and calibrated judges, the sampling pipeline and calibration tooling are worth building once and sharing, the same logic behind deciding what to centralize across your agent stack.
This work sits between your engineering team and your business owners, and it tends to stall because nobody's job covers both sides.
Why Ideas2IT for AI Evaluation and Observability
Ideas2IT closes this gap with Forward Deployed Engineers who embed in your environment from the first day. Delivery is platform-led, so the tooling FDEs use for production sampling and judge calibration is built and maintained by Ideas2IT, and it plugs into the evaluation and observability stack you already run. Nothing gets ripped out, and the rubric stays with your business owner after the engagement ends.
Ideas2IT has been shipping production AI for enterprise clients since 2017, and that has shaped a firm view. Evaluation platforms tend to lead with a dashboard and skip the question of whose judgment passing reflects. A well-instrumented view of the wrong metric does more damage than having no metric, because it gives everyone something to point to while the real problem stays hidden. So every Ideas2IT engagement starts with the business owner's pass or fail calls, and the dashboard comes last.
In our engagements, the first agreement-rate check usually comes back lower than anyone expected.
What the first working session gives you:
- the agreement rate between your current evals and your business owner on one application
- the cause behind each disagreement, mapped to the four drift points above
- a rebuilt rubric for that application, based on where the two disagreed
- a recommendation on which application to take on next
If your evaluation pipelines handle customer or operational data, Ideas2IT is SOC 2 Type II and ISO 27001 certified, and an AWS GenAI Specialist Partner.
Start with the application your business owners trust least
References
- LangChain. State of Agent Engineering. LangChain. June 2026 (survey conducted November to December 2025). https://www.langchain.com/state-of-agent-engineering
- Hamel Husain. Using LLM-as-a-Judge For Evaluation: A Complete Guide. hamel.dev. October 2024. https://hamel.dev/blog/posts/llm-judge/
- Annalisa Szymanski et al. Comparing Criteria Development Across Domain Experts, Lay Users, and Models in Large Language Model Evaluation. arXiv. October 2024. https://arxiv.org/abs/2410.02054